Friday, March 02, 2012

Improving Twitter signal-to-noise ratio with TTYtter extensions

I've been using TTYtter as my primary interface to Twitter for almost a year, and it is still great. In fact, the new releases have made it even better. And the depth of configurability is amazing.

One Twitter user that I follow posts some very cool stuff, but also lots of side-chatter that doesn't interest me. Twitter lets users turn off retweets on a per-user basis, but not the messages to other users (indicated by the presence of the "@" symbol). TTYtter's extensibility makes this easily remedied with a short bit of Perl code that is run during the processing of each Twitter status.
$handle = sub {
my $ref = shift;
my $text = &descape($ref->{'text'});
my $name = &descape($ref->{'user'}->{'name'});
return 0 if (($text =~ /@/i) && ($name =~ /Mr. Noisy/i));

&defaulthandle($ref); #actually print the Twitter message
return 1;
};

The first two bolded lines extract the status text and the name of the person who posted it. The third line checks whether the text is from Mr. Noisy and whether it contains an "@". If so, the function returns a 0 before the code that prints that message to the screen is executed.

Then when I run TTYtter, I include the "-exts=..." flag among the command line arguments:
ttytter -exts="/Users/surly/lib/denoise.pl"
And all of Mr. Noisy's Twitter postings that contain the "@" symbol are filtered out.

Another option is to only include postings from a given user when they receive a certain number of retweets. Here, the bolded lines also show how to use the user's actual Twitter handle (because it's the more common and convenient name to use):

$handle = sub {
my $ref = shift;
my $text = &descape($ref->{'text'});
my $name = &descape($ref->{'user'}->{'name'});
return 0 if (($text =~ /@/i) && ($name =~ /Mr. Noisy/i));
my $rtcount = &descape($ref->{'retweet_count'});
my $sname = &descape($ref->{'user'}->{'screen_name'});
return 0 if (($rtcount < 10) && ($sname =~ /verboseguy/i));

&defaulthandle($ref); #actually print the Twitter message
return 1;
};


I worked out most of this from the TTYtter page on extensions and advanced topics. A partial list of fields that you can extract and filter on are listed in the Twitter documentation on the JSON data representation of a single status object. There is a lot of metadata that could be conceivably used for filtering.

Simpler filtering on the text of Twitter statuses can be carried out using the command-line -filter argument, but these extensions allow far more sophisticated ways of controlling the flow of Twitter information to your screen.
Other extensions that I like:
  • deshortify.pl - which deobfuscates all of those "t.co" hyperlinks.

Thursday, March 17, 2011

TTYtter: a turbo-charged console Twitter client

I finally got around to updating to a real Twitter client again. Twitter now requires that applications use OAuth authentication instead of a standard username/password login, rendering my old command-line Twitter programs obsolete.

But then I found the awesome Perl-based TTYtter. First, unlike a lot of Perl-based applications, you don't have to recursively install lots of other modules to get TTYtter to work. I just installed the single file Perl script, and it worked. The OAuth set-up is clearly described and easy. The benefits of this program are huge! It supports the new-fangled retweets, favoriting, direct-messaging, tracking arbitrary keywords, and searching (I visit search.twitter.com a lot less often). It can retrieve the entire thread for any given Twitter post. If your version of Lynx or cURL supports SSL, TTYtter can use SSL encryption on your Twitter traffic.

There is one Perl module that I would recommend you install though... Term::ReadLine::TTYtter fixes the readline behavior AND gives a cool dynamically-updating character count for what you have typed at the prompt

TTYtter supports Growl notifications, so you can set it up to inform you when you get a direct message or just when there is a new update of any kind. It is highly configurable.

Mac users: Make a file called ".ttytterrc" in your home directory containing just this one line:

urlopen=open -g %U

and then when you use the /url command, TTYtter will open the corresponding URL in your default browser. The "-g" switch opens the page in the background, keeping your Terminal window in the foreground.

One downside to the high degree of configurability is that there is a lot to learn to fully exploit the powers of TTYtter. (I run the program with the following set of command-line switches: ttytter -ssl -readline -notifytype=growl -notifies=dm,reply -notifyquiet -timestamp -filter="/spn\.tw/||/\#FF/".) But the documentation is well-written, and what you get is worth the learning curve.

Friday, July 02, 2010

A history of Google from one user's perspective

I recently thought about some of the ways that Google has revolutionized the Internet. As I started doing a little research, I found that there were more services that they had introduced, which were important at the time and which I still use today, which I was taking for granted. A lot of these memories were triggered by Google's own list of milestones.


1997: Search (Google search actually started in ~1996, but it wasn't until about 1997 that I discovered it.) Prior to Google, searching the Internet was done through Alta Vista which was crappy at finding what I wanted. I spent hours tweaking Boolean expressions, trying to get it to find the right thing. Google easily supplanted it.

2000: An important component in the cleanness and niceness of Google (Search) was the lack of annoying ads which threatened to overtake the rest of the Internet. Google's introduction of AdWords guaranteed a continued peaceful search experience while allowing Google to make money.

2001: Google saves the Usenet archives and makes them way more accessible as Google Groups (which name later came to mean primarily their mailing list/web forum offering, displacing Yahoo(!) Groups which is serviceable but a bit crappier and ad-ridden).

2002: Google News - A better interface for finding news articles (both recent and older stuff) without having to use some specific source or pay for the privilege.

2002: Froogle (now known by the less clever name "Google Shopping"). While never quite ideal, the interface made for a far more pleasant way of finding good prices for purchases on the Internet.

2003: Google acquires Blogger - the free, blogging service which brought you this post.

2004: Google Local is introduced and eventually surpasses other Yellow Pages services in usefulness and intuitiveness.

2004: Gmail revolutionizes web mail which had previously just been a crappy e-mail solution for people without access to *real* e-mail (back when men were men, women were women, and e-mail was text).

2004: Google Scholar: Google indexes academic articles, making them way easier to find. What was it like before Google Scholar? Hell.

2005: Google Maps revolutionizes online maps, providing mouse control over the map for zooming and shifting, bigger and better maps, satellite views, and increasing features and usability. Mapquest was previously my default source for online maps (though I would sometimes use MapBlast for its wonderfully sparse LineDrive driving directions).

2006: Google buys YouTube. At the time, I did not like this because YouTube's interface and video resolution were much worse than available on Google. But YouTube has gradually improved under Google.

2006: Google launches Google Docs & Spreadsheets. While I don't use these for my own purposes, people send me information formatted in such forms frequently enough that having Gmail automatically open them in a usable online viewer makes my life easier.

2007: Google Street View makes it possibly to become familiar with an area and find specific businesses and buildings without ever having to go there.

2007: GOOG-411 allows you to call up 800-GOOG-411 and get directory and business information by speaking location and desired business/location information. I like using it. It's good for when I am trying to accomplish something under a deadline (and don't have time to search from my phone by typing in search terms). [GOOG-411 is unfortunately being done away with in 2010. Microsoft bought TellMe and made BING-411, which is reputedly a good alternative.]

2009: Google Voice: Much of the credit is due to Grand Central, but under Google, this finally got text messaging capabilities and voice mail transcriptions and is just now way better. I don't know whether this will gain wide acceptance or use in the near term, but I believe that in ten years, the more sophisticated phone services which Google Voice allows (ringing many phones from one number, filtering incoming calls to specific phones or voice mail based on who is calling, etc.) will be standard telephone features.

2010: I expect that I will soon appreciate the power of the just released GoogleCL. It makes it possible to access a few Google services from the command line. Currently this is limited to Blogger, Calendar, Contacts, Docs, Picasa, and YouTube.


What this analysis confirms is that (with the exception of Google Voice) no single product that Google has released since 2005 has had the same value for me as Google Maps or Gmail. I'm not sure if this is because Google's new services have not been as vital or simply because I have been adopting fewer new services in the past few years.*

Google Print (started in 2003 and later becoming Google Books) and Google Reader (introduced in 2005) are two obvious contenders that I did not list above because I don't feel that I use them enough that they have impacted my life. Google Translate, I use frequently, but I never remember it surpassing Babelfish. It just became my default translation service somehow. Also Google Talk (2005), Google Calendar (2006), Android (2007), Chrome - Google's web browser (2008 - Mac version, 2010), and Google Wave (2009) have not found their way into my life yet. But even if they never do, the many little continuing improvements to Google Search and Gmail and other products, combined with Google still doing things the way that I would hope they would much of the time (such as offering command-line access to a user's Google data as mentioned above, as well as Google's new encrypted search engine: https://encrypted.google.com/) maintain Google's position in my esteem.


* A third possibility: There is a finite set of web sites that a typical user is going to use enough to be able to recall them and consider them useful. The longer I am on the Internet, the more of those slots are taken up by things that have been around for ~10 years. In the interest of shaking things up a little, let me recommend a new search engine I found when following up on Google's encrypted search:

The criticism of Google's encrypted search is that Google still retains the search records, so privacy is improved but could be better. An alternative is a new search engine called Duck Duck Go. It offers encrypted search AND complete privacy by not logging your IP address or browser information or retaining individual search histories of any type. It supports keyboard shortcuts, YubNub-like searching of other sites ([!g search terms] goes directly to the Google search results for those terms) and easily customizable results pages. It is worth checking out.(back to footnote marker)
UPDATE: 2012: Google announces the imminent demise of Froogle (currently operating under the name "Google Product Search") which will be replaced by "Google Shopping" which is described as "a purely commercial model built on Product Listing Ads." Up until now, the Google Product Search results were unbiased by which companies gave advertising money to Google. This new version will seemingly put the onus for providing product, pricing, and possibly availability information on the retailers, but it seems to also mean that retailers who do not bother to advertise with Google will not have their products appear under the new Google Shopping system. How this compares to the old system for the user will remain to be seen.

My usage of Google services has shifted somewhat since I first wrote this post. I still use Search, Gmail, Maps, StreetView, Google Scholar, YouTube (and Google Video search), and Voice. I find that I rarely use the Usenet search functionality of Google Groups, though I do use its mailing list functionality. Sadly, I have so far not found a use for GoogleCL. Google Translate is now definitely better than Babelfish was. I've started using Google Reader regularly. Despite the way its Google-Plus-associated makeover has made it less responsive and given it an uglier design that wastes screen space, it has the same convenience advantage that Gmail used to lure me away from e-mail clients that were not Web-based. While the interface for Google Books is still not great (giving very little vertical reading space), the fact that it is the only place on the Internet where certain books are available has made it highly useful at times. Google Docs & Google Spreadsheets are useful for real-time collaboration on projects. And after years of waiting for it, in 2011, Google finally improved on TinEye's reverse image search with their own reverse image search, allowing you to upload an image and then finding the same image and/or the most similar images on the Internet.

So despite my complaints about the elimination of services like GOOG-411 and Froogle, this overview has shown me that Google's various services are getting better and becoming more useful (from my perspective).

Sunday, May 30, 2010

Command-line Bayesian Twitter reader with ad-blocking

UPDATE: The method below and the correspond script recently stopped working since Twitter changed their login method to "OAuth". The actual necessary changes will be a) switching to an updated Twitter client like TTYtter (which looks pretty awesome) and b) maybe revising the parsing of the Twitter client output. I've just started working on this and don't know when or if I will release updates. The script still works for Facebook updates, as is.


Following up on my initial post on command-line Bayesian filtering and the subsequent update, I have now generalized the script to incorporate not just Facebook status updates but Twitter posts as well.

I've been refining this script over the last year. In addition to providing a convenient way of incorporating Bayesian filtering in the tracking of posts from Twitter and Facebook, it now has the ability to review a particular Twitter user's posting history (via the "rewind" option) and to whitelist or blacklist arbitrary terms, which can be useful in permanently filtering out undesirable subjects or ads. And it tries to auto-expand those annoying shortened URLs and display the actual title of the web page being referenced.

This script requires that your system has the following programs: links (terminal-based web browser), curl, dbacl (Bayesian decision engine), twyt (command-line Twitter interface).

(I actually use another command line Twitter client (twixer) for following and unfollowing other people's accounts. And, while Twyt should work for posting on Twitter, I often use a third program for posting (twerp) which I started using before I found Twyt.)

Typical usage of the Bayesian twi script:

Teapot:~ surly$ twi
0: [5325528218] StephenAtHome: wearing a mask is
so sweaty. i don’t know how those scooby-doo
villians did it. (Sun Nov 01 00:40:05 2009 via web)
o)k, b)ad, u)rgent, open l)ink, c)opy, add to q)uotes, r)ewind, <CR>=next


The number "0" is just an index that counts down to zero to help identify the status messages you will be processing in this session. The number in brackets comes from the twyt program and is a unique Twitter message ID.

The options presented after the post are:
o)k: Add the post to the "ok" data file (for stuff you want to see more of in the future) and go to the next item.
b)ad: Add the post to the "bad" data file (stuff you don't want to see) and go to the next item.
u)rgent: Add the post to the "urgent" data file and go to the next item. This is a category I came up for for messages that say things like "Party at my place tonight" or "Free T-shirts for the first ten respondents". All I am really doing with them at the moment is highlighting them in a brighter color, but my idea is that in some future revision, these might be actively fetched and brought to my attention. At the moment, so few messages qualify as "urgent" that it's still a half-baked idea.
open l)ink: Opens the first extracted hyperlink in Safari.
c)opy: Copies the text of the post to the OS X system clipboard.
add to q)uotes: Appends the post to a text file with my collection of quotes. In the future, I might cause this to also mark the post as a "favorite" on Twitter, but this is not a priority for me.
r)ewind: The rewind feature was designed to compensate for situations where your Bayesian filter causes posts to filter below your radar and then suddenly another one from the same person bubbles up to the surface, but you don't understand it because you are missing the context. Rewinding causes the program to start going backwards through the locally cached history of all posts (in the "all.d" file) searching for posts from the user in question. It will keep feeding you previous posts as you keep hitting keys (or until you type q for "quit"). This feature only works on Twitter accounts at the moment, due to the way it is extracting the name to grep for.
<CR>=next: You've got to hit the carriage return to advance to the next post. If you type "o" and hit enter, the post will be categorized as "ok". If you just hit enter, your Bayesian filter will learn nothing from this post. Initially, it's good to give your filter as much definite feedback as you can, but once you are happy with its performance, you can just hit enter all the way through if you like.

Importantly, but perhaps not obviously, any set of these commands can be entered for a given post, and they will all be executed. Example:
o)k, b)ad, u)rgent, open l)ink, c)opy, add to q)uotes, r)ewind, <CR>=next

olq
will categorize the item as "ok", open the associated hyperlink, and add the item to the quotes file. There is nothing stopping you from categorizing the item as ok, bad, and urgent, but this will almost certainly just confuse the Bayesian filter.

Finally you will be prompted to "Categorize which other posts as ok?"


When the program is finished processing all the new status messages, it will post an accuracy rating for the current session (basically, if you don't mark any of the "ok" messages as bad or correct any of the "bad" ones to be ok, it thinks it has 100% accuracy). You can use this as a rough metric for how good the current training level is.

Limitations: The current version of Twyt does not seem to be picking up the newfangled "Retweet" posts. Based on the messages that I am missing, this is something of a net advantage.

The twi script can be found here.

Saturday, March 27, 2010

A Palm user tries to convert to the iPod touch

I finally bought an iPod touch. I had wanted one for two years. I really started to want one last year, when Apple started allowing developers to write applications for the iPhone OS. With the release of the 3.0 version of the iPhone OS, it had seemed that there was finally enough functionality to allow the iPod touch to serve as my primary PDA.

First reactions: Even though I had seen it before and played with it in stores, the actual experience of owning a device with such an amazing and cool-looking interface has exceeded my expectations.

Something about many of the apps available from the iTunes Store sort of immediately turned me off though. Lots of them have a desperate commercial aura that I associate with Windows shareware programs. Many of the free programs are prominently labelled as "FREE" or "LITE" and some have ads in them. It's usually apparent after running a program whether it feels right. Since I prefer using open source programs, the iPhone apps scene, where everyone has to pay $100 annually to have their programs available to be bought or downloaded, feels kind of constrained.

Fortunately there are exceptions. The programs I list below (in particular, Instapaper and Simplenote) have great interfaces and are a joy to use.

A comparison of Palm and iPhone programs for a few functions.

Function: General purpose maps
Palm program: Mapopolis
iPhone equivalent: offmaps
Comments: offmaps is much cheaper (though this is thanks to the OpenStreetMaps initiative for free map data), but it can't search for streets without an Internet connection. Also it frequently doesn't have the amount of cached detail that I had hoped it would have. I'll bet there's a better maps program out there, but I haven't found it yet.
Advantage:Palm*

Function: GPS turn-by-turn navigation
Palm program: TomTom
iPhone equivalent: TomTom? Navigon?
Comments: Prices are comparable, but for the iPod touch user, it's still not clear whether any GPS software will interface with an external Bluetooth GPS (which was the norm for the Palm). It seems like the only official way of doing it is to pay TomTom $200 ($100 for the GPS which interfaces to the iPod, and $100 for the software).
Advantage: Palm*

Function: Offline web page reading
Palm program: Plucker
iPhone equivalent: Instapaper
Comments: Plucker is free. Equivalent Instapaper functionality costs a few bucks. Also, since I had built my own plucking script, it was convenient to pluck both web pages and HTML and text pages on my computer. Instapaper only works for things that are already online. But Instapaper allows me to mark things for offline reading from any computer. (Actually Instapaper does give you an e-mail address that you can send an e-mail to, and the contents will show up in your list of things to read. However, the Instapaper interface shifted a little after I wrote this review. The new version of the app wasn't quite as fast, and the main new features seemed to be sharing/"liking"-oriented. Ultimately, in mid-2012, the app just unexpectedly stopped synching new content. I tried to redownload everything, but in the process I lost all articles that I had already downloaded (never to be recovered). The reason? The Instapaper servers had been modified to work with a still newer version of Instapaper, but this version would not run on my (admittedly older) iPod touch. That is, the developer broke my version of the app because he decided that he only wanted to support iOS 5 (which was being used by the vast majority of users). [This should perhaps not surprise me as this is also the developer who made all of his users change their usernames from short names that they had chosen to e-mail addresses.] So the alternative functioning app that I found that fulfills the same function is Readability. It loads terribly slowly and timed out on synching one huge text file, but it is otherwise fine. End of rant. )
Advantage: Palm


PDF reading is definitely superior on the iPod touch (I recommend buying GoodReader), but for some reason it's not convenient enough that I have gotten into the habit of reading PDFs on it.

Address book functionality is adequate on both.

Overall, in terms of PDA functions, it's kind of a draw. I've now owned the iPod touch for six months. I have my Address Book information on it. I use it regularly for reading web pages downloaded through Instapaper.

The killer feature of the iPod touch is the iPod features themselves. I use it for listening to podcasts and music all the time. The convenient and automatic syncing of stuff to the iPod and its intuitive interface are the key features that make it so much better than any competing products that I have played with. The Palm was never even close to a decent mp3 player. Combined with the iPod touch's better battery life (the Palm is a color model), this is the reason that I stopped carrying the Palm in favor of the iPod touch.

I sync text files over to the iPod touch using Simplenote, but it has to be done manually. (I could easily automate syncing from the computer to the Simplenote web site, but in order to sync text files with the iPod touch, one must run the Simplenote program while the iPod has an Internet connection.) With the Palm, I had it set up so that everything would sync pretty much automatically. Instapaper has the same syncing problem. One advantage to Simplenote though is that the syncing works in both directions without any contemplation on my part so I can take notes on the iPod touch and sync them back to my computer as well as going the other way (whereas on my Palm, I pretty much just synced from the Palm to my computer). In truth, I am not using the text files feature so much on the iPod.

I'm starting to experience gadgetlust again. I want to have something that I can carry around that I can modify... like something that could run Perl or Python scripts. This is forbidden on the iPod touch. A cheap Android device looks slightly appealing. Unfortunately the unlocked phones are still quite expensive.

There are a lot of cool programs for the iPod touch (the Dropbox client, Google Earth, Pandora). Basically, for Internet functionality the iPod touch blows away the Palm, but for the few things I want to do on a regular basis (other than listen to audio files) - read text files, read downloaded web pages, look at offline maps, turn-by-turn navigation - the Palm is actually still as good or better. Maybe this is because I acquired this functionality over years of fiddling with things and finding the right software. Presumably I will find (and pay for) better software for some functions on the iPod touch, but whether I will be able to tinker as much and optimize some otherwise suboptimal features, remains to be seen.


* UPDATE: The new Mapquest iPhone app may improve map capabilities for the iPhone Touch significantly. (Back to the footnote pointer)

ANOTHER UPDATE: It turns out that it is possible to use HTML5 and Javascript to program "web apps" which are almost as good as a regular iPhone App (mainly lacking the ability to access iPhone sensors). It is possible to save these apps to your device and use them even when offline. This may counteract some of my above criticisms of the iPhone.

UPDATE 3: A collection of iPhone web apps, with reviews, can be found at OpenAppMkt. However, it's unclear how well they work. I tried PieGuy (a Pac-Man-like game) on my second generation iPod touch, and it didn't work at all. I also recall Checklist as being wonky, behaving OK sometimes, but then losing its state at other times. Your mileage may vary.
UPDATE 4: This post is now largely of historical value as the abilities and variety of iOS apps have continued to improve and workarounds have been devised to address problems. (Though it is still as of 2012 necessary to actually open the SimpleNote app while the device has an Internet connection in order to make it sync.)

Friday, February 19, 2010

The One Book List

Back in the early days of the World Wide Web, there was a thing called "The One Book List". It was started in 1994 by Paul Phillips when he posted to the rec.arts.books newsgroup:
I would like for each of you to decide on a single book that you would most like for the world to read for inclusion in the list. The book that, for you, was the most influential, or thought-provoking, or enjoyable, or moving, or philosophically powerful, or deep in some sense you cannot properly define, or any other criteria you wish to set.
Hundreds of people responded to his request, and he eventually accumulated a set of stellar recommendations from people all over the proto-Web, including Douglas Adams, who recommended The Blind Watchmaker by Richard Dawkins, and Douglas Hofstadter, who recommended The Catcher in the Rye.

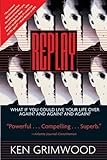
I often used to browse through the One Book List Replay when looking for a great book. It was from this list that I found Replay by Ken Grimwood. It takes a novel concept involving replaying events, explores all the permutations, and ultimately comments on the role of human decisions in life. Replay is a thought-provoking and entertaining book that has stuck with me ever since I read it.

When I looked for the list again recently, I found that it had essentially disappeared from the Internet. The only place you can find it now is through the Wayback Machine which has a copy of the original front page of the One Book List site (last updated in 1998) and the the list itself. If you are looking for a great reading experience, the One Book List is still a great place to start your search.

Tuesday, February 09, 2010

Comics about Science

I've loved comic strips as far back as I can remember, particularly Calvin and Hobbes and The Far Side. But in the last few years, I've discovered a whole lot more comics to my liking, and many that appeal to those of a scientific mindset.

xkcd may be the first of the Internet-based comics to break through into the mainstream, on the basis of its strong appeal to people interested in science, technology, humor, and sometimes relationships. It has now been around for almost four and a half years, amassing nearly 700 strips and is one of the most successful online comics (a.k.a, "webcomics").

If you want humor that is even more deeply connected to math and physics, try Abstruse Goose. One of my favorites is called All You Zombies.

I also enjoy this web comic about Charles Babbage and Ada Lovelace and their giant Difference Engine. And crime-fighting.

My current favorite online comic is Dresden Codak. The artwork is gorgeous. Every comic has an interesting idea in it (often something about science or philosophy), and it is relentlessly inventive, unafraid of trying new things.

You can support independent comic strips like this by buying their merchandise. (I do!) You can currently buy Dresden Codak comic strip prints and T-shirts and soon there should be a Dresden Codak book, compiling the artist's work.

There are of course many comic books which use the medium simply for explaining scientific concepts, Larry Gonick's Cartoon Guides to Everything being the best-known example.

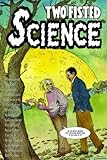
[Two-Fisted Science] Two-Fisted Science by Jim Ottaviani is a comic book with many different stories, all featuring real scientists and mathematicians, including Einstein, Newton, Galileo, Leibniz, Bertrand Russell, Bethe, Pauli, Heisenberg, Bohr, Oppenheimer, and Feynman!

Bertrand Russsell is also featured in Logicomix. I am currently reading it and will post a review when I'm done.

Thanks to some combination of increases in the role of science in society, interest in science, and leisure time, we now have a lot more opportunities to consume science-based literature and entertainment. Enjoy!

Thursday, October 08, 2009

Wednesday, September 30, 2009

Saturday, August 15, 2009

Pinboard.in - the second coming of del.icio.us?

I used to love del.icio.us. Then Yahoo bought it and turned it into delicious.com. While the new version has some good features, I overall find it too slow and bogged down in fancy, unnecessary ornation. In many ways, I prefer the sparseness of the old design.

Pinboard was recently announced as the cure for such problems. Joshua Schachter (creator of del.icio.us) seems to be an unofficial, in-the-background consultant on this project. He posts on the Pinboard Google group.

One neat new feature that Pinboard has is a quick bookmark-this-without-tagging option which automatically puts things in a special, private "to read" pile. This is intended to work much like the Instapaper model.

The last essential piece of a bookmarking archive is automatically saving the HTML and other contents of a bookmarked page, preserving a locally cached copy for all time. The Pinboard developer is promising this in the future, for a fee.

There is a sign-up fee of ~$5. I paid it because, after seeing bookmarking site after bookmarking site go under or decay, I want to believe that one can be done right. I want to like bookmarking again. For now, I do.

Saturday, August 08, 2009

Life! Don't talk to me about life!

>ask Marvin about the object of the game

"Being clever doesn't always make you happy, you know. Look at me, brain the size of a planet, how many points do you think I've got? Minus thirty zillion at the last count."

The amazing Douglas Adams/Infocom collaboration, the Hitchhiker's Guide to the Galaxy text adventure game, is playable online in Java or Flash (with added illustrations).


Marvin was so popular at one point that he recorded and released a few songs (more details on Wikipedia... definitely check them out if you get the chance), and there was even a Marvin Depreciation Society.


There is apparently going to be a sixth book in the Hitchhiker's series, written by the guy who writes those Artemis Fowl books. It's going to be called: And Another Thing... [All of the titles for the five books in the Hitchhikers' Guide series were phrases that appeared somewhere in the first book. I was hoping that any sixth book would be called "Oh no, not again" (which was what the bowl of petunias thought when it was brought into existence over Magrathea before crashing into the planet).] The book releases on October 12th, 2009. According to the Amazon page: "It features a pantheon of unemployed gods, everyone's favorite renegade Galactic President, a lovestruck green alien, an irritating computer, and at least one very large slab of cheese. " And Arthur and Marvin will be back!

Upgrading the Bayesian-filtered status reader

In a previous post, I described my assembly of a command-line program for Bayesian filtering and presentation of Facebook statuses. After a while, constantly pulling down the RSS feed (via curl) and seeing the same statuses for certain people, day after day until they expired, kind of wore on me, so I went looking for a simple feed reader. There were command-line feed readers that looked more appealing to me (Canto and Newsbeuter) but they required newer versions of Python or some series of installations of things that were not available in a sufficiently upgraded form in Fink. So I tried rawdog which is written in Python and only requires the easily installed feedparser. It seemed like it was modifiable to do what I wanted, and I even went so far as to post a triumphant blog post about my success with getting it to properly parse my Facebook feed and deliver it to my Bayesian-filtering/displaying script. And then the next day, it went haywire and started reshowing me things I had already seen and dismissed.

So.

I decided to do everything myself. I was already partially parsing the RSS feed, so I just went a little further and parsed out the post date and compared it with the date when I last looked through the posts. (This seemed daunting until I found out that Perl already has time functions built in.) Finally I coded in dumping the output to a text file, as well as to the screen. Now the command can work on its own or have its output easily combined with my separate Twitter Bayesian filter which is a bit more sophisticated and which does a nice job of increasing my local Twitter signal-to-noise ratio. I intend to post about it someday.

The code for stati.pl is here.

Thursday, July 30, 2009

The Hardest Logic Puzzle Ever

The Hardest Logic Puzzle Ever came up recently in a Metafilter post, but it linked to a site that gave a very poor explanation of the puzzle and no credit to the original author, Raymond Smullyan (creator of the logic puzzles involving people who always tell the truth and people who always lie).

George Boolos wrote up a nice description of the Hardest Logic Puzzle Ever, including clarifications and breaking the puzzle down into more manageable sub-puzzles. The puzzle goes a step beyond the liars and truthtellers by introducing a third entity: someone who just gives random responses. And they all speak in some completely foreign language. If you solve the whole thing, you can claim that you solved the Hardest Logic Puzzle Ever! It is a bit of a project and benefits from contemplation. It's one of my more memorable puzzle experiences.

George Boolos also once gave a short talk on Gödel's second incompleteness theorem, using only one-syllable words. The text is available here in PDF.

And Smullyan does more than just make puzzles! He is a professor of philosophy at Indiana University and has done important work on extending the applicability of Gödel's incompleteness theorems.

Tuesday, July 07, 2009

How I found Ian Shoales

I remember sitting in a parking lot, waiting for some unrelated event, listening to this little snippet of audio over and over, trying to extract enough of the words that I could figure out what to Google to determine the source. The guy was talking really fast and the other stuff on the cassette seemed to be taped off of the radio... Was it a radio program? The words could have been ungooglable.

I had found this cassette in a box with a bunch of discarded tapes and CDs, left behind by whoever had previously been working in my room. None of it was as tantalizing as this.

It featured someone named Ian in an office fencing with his secretary and spouting diatribes and sardonic top-ten lists before being accosted surreally by an inflating fat man satirizing the stereotypical James Bond (or Dashiell Hammett) villain, complete with henchmen.

I googled my transcriptions and came up with nothing. Then I tried [ian radio monologue -laura] on Google Groups, which turned up a reference to an Ian Shoales and Duck's Breath Mystery Theatre on NPR.

Ian Shoales: Think of him as kind of like Oscar the Grouch, only less muppety and on speed. He is a parody of a critic. Not unlike Stephen Colbert.

He has a web site and his alter ego, Merle Kessler, regularly posts to a blog.

Here is one of his self-introductions:
Hi, I'm Ian Shoales, the-semi-eminent, acerbic social critic. Perhaps you've heard of me. Perhaps you've noticed my hardhitting commentaries on "All Things Considered" and "Nightline," or in USA Today? My trademark, "I gotta go"? That Ian Shoales? Is my name a word in your household? When you see the crossword puzzle clue "bitter, negative, cynical," do you write "Shoalesian" in the boxes, whether it fits or not? I know I do.
Ian on the concept of the state lottery: "Luck gets a bureaucracy."

"I don't like people who speak French in public places. This includes the French."

Ian Shoales on ... himself again:
I admit it freely -- I'm not a positive thinker. On Star Trek, the beautiful alien with the green hair and the taut belly would always say to Captain Kirk, "Oh one called Jim, what is this thing you call a kiss?" If that alien were here today (and in my Perfect World, believe me, she would be), she would gaze at me lovingly and say, "Oh one called Ian, what is this thing you call a sneer?" That's the kind of guy I am. Captain Kirk and I both want the same thing: the whole-hearted devotion of a naive alien. And if certain things stand in our way -- Klingons for Kirk, reality for me -- well, we just have to suck in our guts, set the phasers on Stun, and hope for the best.
Ian Shoales on Twitter:
Posts traditionally have been things like "I'm drinking coffee!" or "A bird flew by!" or "I just shot my parents!". These posts are called tweets. Users of Twitter call each other Tweeple. And haters of Twitter are called Twaitors. It's all a little too *smurfish* for me.
Ian can be heard on KQED (which fortunately has streaming audio), Saturdays and Sundays at around 5:35am.

Saturday, June 27, 2009

Custom Iron-on Decals for T-shirts (or Whatever)

If you have an iron and an inkjet printer, you can make your own iron-on decals. The thermal transfer paper runs about $1 per sheet. This one is supposed to be one of the best.

The easiest way to do this is to use white fabric. Then you can simply scale the picture you want to print and take the mirror image (if getting the orientation correct matters for your image) and print it onto the special thermal transfer paper. Then you press the paper onto the fabric (pre-ironed, so it's smooth) with a hot iron (though not against an ironing board, because an ironing board is soft and the transfer will become distorted... one needs a hard, flat surface).

It's really not that difficult, and making something like this gives a feeling of satisfaction. My first test is shown here. My plan is to custom-design a T-shirt. Maybe with discreet logos on the sleeves.


If you need ideas for designs, check out some of the cool shirts at Topatoco:


Wednesday, June 17, 2009

Synthesizing a word for a set of zero

I felt like making up a word for when you have zero of something. Like if three is a triple, and two is a double, then one is a single, but what is zero?

There's a good generic term for such a word: a tuple. For n=4 and above, all the tuples end in "-uple" (quandruple, quintuple, sextuple,...). Maybe they should be called the "uples". And Wikipedia has an entry for n=0. It looks like this:
0: Empty tuple; Unit
I don't like it much. Since all the other prefixes come from some variant of the Latin word for the number, I decided to start with the Latin word for zero. Of course, the Romans didn't have a symbol for zero. Some hold that the Babylonians were the first to come up with one and that this idea propagated around and eventually the Latin alphabet picked up words for zero in the Middle Ages: cifra and zephyrum. (The English cognate would be cipher.) Therefore, I propose zephle as the zero-tuple. Or else zerple. "Zephle" is probably a more genunine fake tuple, but "zerple" (pronounced as ZEER-pul) is more self-explanatory and fun to say. Zerpledecker bus. Zerple cheesburger. Zerple date. Identical zerplets. See?

Word most likely to be confused for zero-tuple: nonuple. It's when you have nine of something. There's a really long list of such words here.

Saturday, June 06, 2009

Automated self-monitoring

Looking for a way to self-monitor my working habits, I decided to write a script to analyze my notebook file and determine on which dates I had made an entry. Ideally, I ought to be working and making notes on my progress every day.

I decided to grep through the file for datestamps and form something like an ASCII sparkline, indicating whether I had made at least one entry on a given day.

The output for the last couple of months looks like this:
.|.|...|......|...|...||.|..||||....||........|..|..|||.

It looks even more badass displayed on my desktop via Geektool. I am also displaying the actual number of entries for each day immediately below the corresponding sparkline symbol. Admittedly, this contradicts the idea of displaying the information in tiny graphical form. I may eventually switch to something like this:
.|.-...:......-...-...--.:..-::-....::........-..-..---.


This is almost like Benjamin Franklin's system for reinforcing his 13 virtues. Admittedly, I am only reinforcing one virtue now, but I have a few other habits that I have been monitoring with my all-purpose tracking script, and these are ripe for display and correlation with other behaviors.

Friday, June 05, 2009

My 1mm-thick PDA backup system

You may have heard of the "Hipster PDA". It started as a joke that a bunch of notecards could be used like a PDA without all the electricity and technology. Then it caught on. There are elements of this that I like (particularly the creativity and do-it-yourself-ness), but it wasn't what I wanted.

The problem that motivated me: Every once in a while my PDA runs out of charge and/or loses all its data. As everything is backed up on my laptop, this is mainly just inconvenient. But when I suddenly need some vital bit of information that is on said PDA, it suddenly shifts to serious nuisance.

My first solution was to simply print out my calendar (which I keep in the plain text remind format) in 4-up form, fold it up, and keep it in my back pocket. And I found that I liked this because it is often easier to pull out and immediately access the information that I want. (It is particularly useful when going on a trip and having flights, times, hotels, and rental car places all listed on a little rectangle of paper.)

This eventually developed into a full script. This script currently collects the following things into a single text file. 0) The current date, to ensure freshness. 1) The output of my remind calendar, excluding boring things. 2) A little address book. I started by extracting specific contact information for specific people from the OS X Address Book via a little command line program called contacts. Then I wised up and started extracting everyone who has an asterisk after their name, allowing me to easily switch people in and out of my short list. (This is something I would like to automate someday.) 3) Some things that I have hard-coded into the program, including public transportation information, phone numbers for taxis, directions to places that I rarely go to, and business hours for a few places. 4) A tiny calendar. I initially thought of setting this up to grab the last, current, and next months from the UNIX cal program, but then I thought of the ingenious thumb calendar which allows a bunch of months to be compactly fit into a small area. And I realized that I could make my own. 5) And finally, my shopping list as extracted from my todo.txt to-do list.

[The only thing that I would like to get on there that I haven't figure out yet is a ruler, along the edge. This will likely require monkeying with PostScript or something.]

Here's the pared down script:

#!/usr/bin/perl -w

$fname="/Users/Surly/remind.txt";
open(INFO,$fname);
@lines = ;
close(INFO);
$outfile="hpda.txt";

open(OUTFO, ">$outfile");

$datestamp=`/bin/date "+%y%m%d"`;
print OUTFO $datestamp;


$i=0;
while($lines[$i])#assuming we initially have a numbered subtitle
{ $rem=(($lines[$i]=~/^rem/)|($lines[$i]=~/^REM/));
$pass=((($lines[$i]!~/^[;#\n]/)&$rem)&($lines[$i]!~/growlnotify/));
$pass=$pass & ($lines[$i]!~/boring/);

if ($pass)
#ignore comments and growlnotifys and commands and only pass REMs
{$lines[$i]=~s/^rem //;$lines[$i]=~s/^REM //;
$lines[$i]=~s/ msg/:/;$lines[$i]=~s/ MSG/:/;
print OUTFO $lines[$i];
}
$i++;
}

print OUTFO "===contacts=========\n";
$a1=`contacts -H -f "%n %mp %wp %hp" Cleo`;
$a1=~s/-/./g; print OUTFO $a1;
$a1=`contacts -H -f "%n %wp %op" Popeye`;
print OUTFO $a1;
$a1=`contacts -H -f "%n %mp %e" Betty`;
print OUTFO $a1;
$a1=`contacts -H -f "%n %mp %wp %op %a" Snidely`;
$a1=~s/\n\n/\n/g; print OUTFO $a1;
$a1=`contacts -H -f "%n %mp" "*"`;
$a1=~s/-/ /g;print OUTFO $a1;
$a1=`contacts -H -f "%n %mp %a" God`;
$a1=~s/\n\n/\n/g; print OUTFO $a1;

print OUTFO "===random stuff====\n";
print OUTFO "The Hamburglar's place: Practice, practice, practice, and take a left.\n";
print OUTFO "Library: open until 8pm.\n";
print OUTFO "===thumb calendar=====\n";#thumbcalendar.com
print OUTFO " Su Mo Tu We Th Fr Sa JUL (31)\n";
print OUTFO " Su Mo Tu We Th Fr Sa SEP (30)\n";
print OUTFO " 01 02 03 04 05 06 07\n";
print OUTFO "01 02 03 04 05 06 07 08 09 10 11 12 13 14\n";
print OUTFO "08 09 10 11 12 13 14 15 16 17 18 19 20 21\n";
print OUTFO "15 16 17 18 19 20 21 22 23 24 25 26 27 28\n";
print OUTFO "22 23 24 25 26 27 28 29 30 31\n";
print OUTFO "29 30 31\n";
print OUTFO " Su Mo Tu We Th Fr Sa JUN (31)\n";
print OUTFO " Su Mo Tu We Th Fr Sa AUG (31)\n";
print OUTFO "===\@shopping========\n";

$fname="/Users/Surly/todo.txt";
open(INFO,$fname);
@lines = ;
close(INFO);

$i=0;
while($lines[$i+1]){$i++;}

while($i>=0)
{ $pass=(($lines[$i]!~/^x /));
$pass=$pass & (($lines[$i]!~/\@office/));
$pass=$pass & ($lines[$i]=~/buy/);
$pass=$pass & ($lines[$i]!~/\@online/);

if ($pass)
{$lines[$i]=~s/ \@shopping//;
$lines[$i]=~s/^buy //;
print OUTFO $lines[$i];
}
$i--;
}

close(OUTFO);

Thursday, June 04, 2009

The Surly Teabag Consumer Report on the Last.fm subscription

So I wanted to play a particular album. It looked like it was playable from last.fm (under their current you-can-play-any-streamable-track-3-times-for-free policy) but that seemed to entail clicking each and every one of those little play buttons. I wanted to stream a continuous set of songs so I could work without interruption. So I anted up the 3 bucks for a one-month subscription to last.fm. My conclusion is that it is worth it, but first some details:

The last.fm playlist creator has a very clicky interface. What I wanted was just to click on something near the album and put the whole thing in a playlist. But there seems to be no option for that. So you've got to find every song you want to hear and click on it a couple of times to get it on the playlist. At least dialog boxes can be dismissed by hitting the return key. Before you can play a playlist, it needs at least 45 playable tracks by 15 different artists, so be prepared to do a lot of clicking.

Now the good news. It is freaking awesome: I discovered a bunch of new songs that I loved, so I went out and bought them. This is probably the most efficient way to track down those elusive tracks that I want to listen to over and over. Thank you, last.fm.

Saturday, May 09, 2009

In search of the ideal Twitter command-line client

After testing out a bunch of candidates, my new default command-line Twitter client is Twyt. Do not be fooled by the spartan front page. Active development is taking place. It's written in Python and (as of version 0.9.2) has the virtue of offering the following command-line options for the "check stati of friends" command:

-s SINCE, --since=SINCE
The date or ID of a message to list status messages
from.
-P PAGE, --page=PAGE Lists the PAGEth page of status updates
-n COUNT, --count=COUNT
The number of statuses to retrieve (max 200)

Unfortunately, it seems to be suffering from the same malady as other programs: No matter what value I put in for the --since flag, I still get the same 20 stati... The --page flag does work though, and the --count flag is doing something...

However, I also like the twixer client because it has implemented a few commands that I have not found in any other command line program. According to its command line options, it can 1) list your friends, 2) list your followers, 3) show the little information box on a user, and 4) delete stati and direct messages.

Unfortunately (and maybe I am doing something wrong here), but as of version 0.1.1, it will only show the little information box on me, no matter who I put in. But status deletion works great!